 PredictionToolkit
What is Pendulum Flow Orderbook Archive?
The archive is organized into hourly Parquet files, letting you choose a bounded interval and read selected columns or row groups with DuckDB or another Parquet engine. Rebuilding depth needs both full book snapshots and subsequent price_change rows; trade prices alone are insufficient.
Capture eras must remain visible in any derived dataset. V3 includes receive-time, witness and sequence information, while earlier collectors differ in schema and fidelity. An hour awaiting publication is different from a missing recording; audit gaps and hour boundaries rather than assuming continuous coverage.
Who it is for
- Researchers rebuilding historical order books.
- Engineers building local Polymarket datasets.
- Analysts requiring inspectable provenance and gaps.
Dataset scope and fields
- Hourly Parquet
Read a chosen hour without downloading everything.
- Snapshots and deltas
Combine book snapshots and price_change rows for resting quantities.
- Trades and lifecycle
Access trade prices, new markets, resolutions and tick-size changes where recorded.
- V3 capture provenance
Inspect receive timestamps, witness fields and sequence data.
- Checksums and manifests
Verify file hashes and review event counts before processing.
- Coverage audit
Review absent hours and era-specific collection limits.
- Remote columnar reads
Use DuckDB or another reader to select columns and row groups.
Data preparation and analysis
Reconstruct one book
Choose an audited V3 interval, load a snapshot and apply token-level changes in receive order, handling the hour boundary.
Study size sensitivity
Rebuild both sides, walk price levels for a chosen size and compare with the same-time midpoint.
Keep an inspectable extract
Store source paths, checksums, capture era and filters with the derived dataset.
Pricing and total cost
Public downloads are free without an account or API key. Donations support capture, storage and delivery.
Dataset access and delivery
- Select a time range in the coverage index and read that era’s format.
- Inspect the hourly manifest and checksum, then query one market and a few columns.
- Sort by the era’s time/sequence semantics and record missing intervals.
Useful links
What to check
- Capture versions have different schemas and fidelity.
- V3 receive timestamps use microseconds; older mirrored data commonly uses milliseconds.
- Collector sequences are not global exchange ordering across machines.
- Publication delay differs from a missing recorded hour.
- Hourly files can exceed 1 GB; use a columnar engine rather than a spreadsheet.
A closer look
Ratings & reviews
User reviews 0
The main score switches to user ratings after 5 published reviews.
A specific example helps the next person choose the right tool.
Related tools
Browse category
Retrieve recorded book ladders, sports mappings and aligned price bars for research and replay.
- Access API · MCP

UTC market-day downloads and browser book-and-trade replay for studying how recorded execution costs change with order size.
- Access Web · API
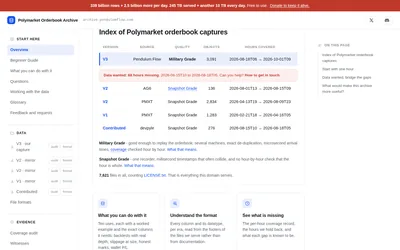
Download earlier Polymarket book captures from the public mirror and inspect the coverage of each era.
Frequently asked questions about Pendulum Flow Orderbook Archive
Must I download every hour?
Choose a bounded range and filter Parquet columns and row groups.
Which events reconstruct resting depth?
Book snapshots plus price_change deltas.
Is it one uniform capture?
No. Older eras use other collectors; inspect the version and audit.
Can I verify downloads?
Prefixes publish checksums; V3 hours also have manifests.